Run AI models locally from plain PHP.
Generate images, text, speech and video with small Hugging Face models — right inside your Laravel or PHP app.
No Python. No API bills. No data leaving your server.
composer require php-loves-ai/multimodal-ai-runner
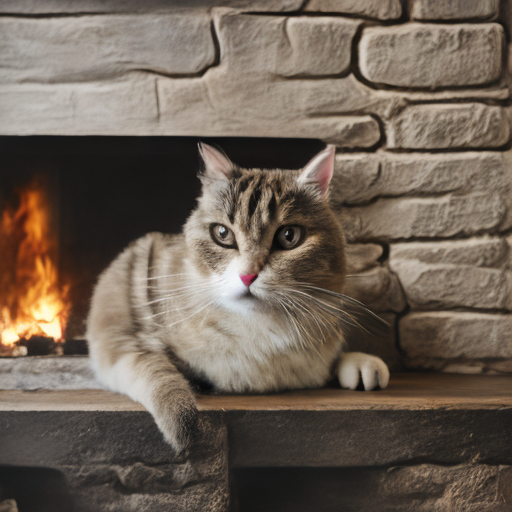
“a cozy cat by the fireplace”
cat.png · 512×512
Works with models from the Hugging Face Hub
One package. Eight AI superpowers.
Each task has its own runner, and one runner serves many models. Install only the ones you need.
Text to Image
Turn a prompt into a picture with any Diffusers model.
Text to Text
Answer prompts, summarize and continue text with LLMs.
Image to Text
Describe an image or ask questions about what's in it.
Speech to Text
Transcribe and translate audio, with timestamps for subtitles.
Text to Speech
Read any text aloud into an audio file.
Image to Image
Upscale photos or redraw them following a prompt.
Text to Video
Generate short video clips from a text prompt.
Image to Video
Bring a still image to life as an animated clip.
Feels like native PHP.
Because it is.
Named arguments, typed exceptions, zero config. The runner finds pulled models in your project by itself.
use PhpLovesAi\Runner\TextToImage;

// Finds the runner and the pulled model by itself.
$image = (new TextToImage())->generate(
    model: 'stabilityai/sd-turbo',
    prompt: 'a cozy cat by the fireplace',
    outputPath: storage_path('app/cat.png'),
    steps: 1,
    guidanceScale: 0.0,
);
use PhpLovesAi\Runner\TextToText;
$answer = (new TextToText())->generate(
model: 'Qwen/Qwen2.5-0.5B-Instruct',
prompt: 'Summarize in one sentence: PHP is a popular scripting language...',
systemPrompt: 'You are a concise assistant.',
maxNewTokens: 100,
temperature: 0.0,
);use PhpLovesAi\Runner\ImageToText;
$answer = (new ImageToText())->generate(
model: 'HuggingFaceTB/SmolVLM-256M-Instruct',
imagePath: storage_path('app/photo.jpg'),
prompt: 'Is there any text in this image? Write it out.',
maxNewTokens: 100,
);use PhpLovesAi\Runner\SpeechToText;
$speechToText = new SpeechToText();
$english = $speechToText->transcribe(
model: 'openai/whisper-small',
audioPath: storage_path('app/interview-uk.mp3'),
language: 'uk',
translate: true,
);
// [['start' => 0.0, 'end' => 5.56, 'text' => '...'], ...]
$segments = $speechToText->transcribeWithTimestamps('openai/whisper-tiny', $path);use PhpLovesAi\Runner\TextToSpeech;
$file = (new TextToSpeech())->speak(
model: 'facebook/mms-tts-eng',
text: 'PHP loves AI, and now it can speak.',
outputPath: storage_path('app/hello.mp3'),
speed: 0.9,
);use PhpLovesAi\Runner\ImageToImage;
$painting = (new ImageToImage())->transform(
model: 'stabilityai/sd-turbo',
imagePath: storage_path('app/photo.jpg'),
outputPath: storage_path('app/painting.png'),
prompt: 'a watercolor painting',
strength: 0.6,
steps: 2,
guidanceScale: 0.0,
);use PhpLovesAi\Runner\TextToVideo;
$clip = (new TextToVideo())->generate(
model: 'Wan-AI/Wan2.1-T2V-1.3B-Diffusers',
prompt: 'a cat walking through tall grass',
outputPath: storage_path('app/cat.mp4'),
frames: 33,
fps: 16,
);use PhpLovesAi\Runner\ImageToVideo;
$clip = (new ImageToVideo())->generate(
model: 'Wan-AI/Wan2.1-I2V-14B-480P-Diffusers',
imagePath: storage_path('app/photo.jpg'),
outputPath: storage_path('app/clip.mp4'),
prompt: 'the camera slowly zooms out',
frames: 33,
fps: 16,
);From zero to inference in three commands.
The Composer package is tiny. Prebuilt runner binaries and model weights live in your project's .local directory — never in Git.
Install
Add the package and download the runners for your platform.
composer require php-loves-ai/multimodal-ai-runner
vendor/bin/loves-ai setup text-to-image
Pull a model
Only the PyTorch files the runners can read — often half the size.
vendor/bin/loves-ai pull stabilityai/sd-turbo
Run it
Call it from a controller, a command or a queued job — or straight from the terminal.
// PHP
(new TextToImage())->generate(...);
# CLI
vendor/bin/loves-ai text-to-image stabilityai/sd-turbo "a cozy cat by the fireplace"
Private, predictable, yours.
Data stays on your server
Inference runs locally. Nothing is sent to a cloud AI service.
No per-token bills
Pull a model once and run it as often as you like.
No Python to install
Runners ship as self-contained binaries, called via Symfony Process.
Queue-friendly
Fits naturally into Laravel jobs, workers and Docker containers.
Typed exceptions
Know exactly what went wrong: missing runner, model or gated access.
Zero path config
Everything lives in .local/ — CLI, php-fpm and workers all agree.
Give your PHP app a brain today.
One Composer command and your app can see, hear, speak, write and imagine.
composer require php-loves-ai/multimodal-ai-runner